

By Nchetachi Chukwuajah
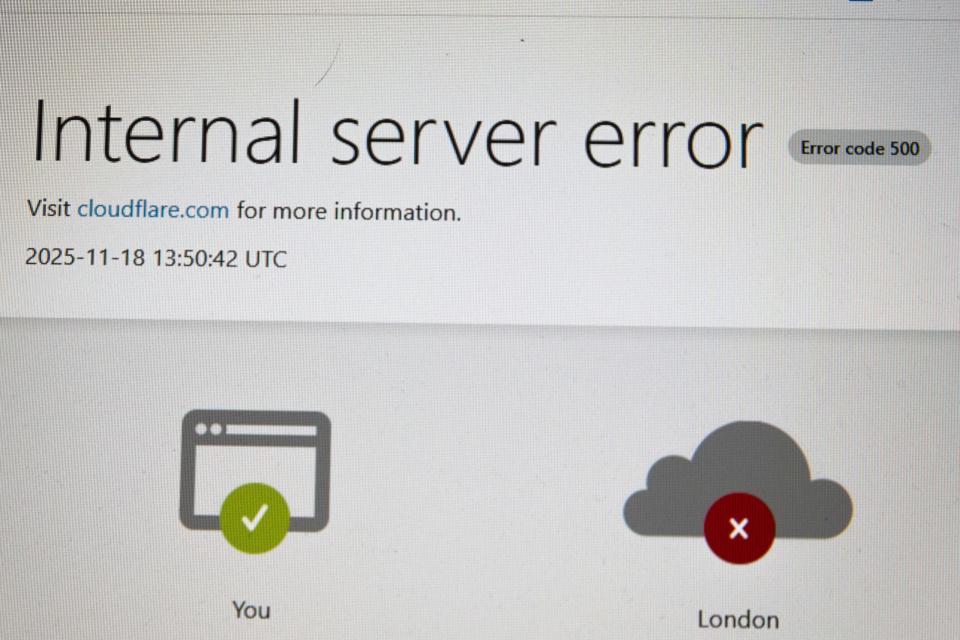
A web infrastructure firm, Cloudflare, has apologised to its customers following global internet disruption that saw many websites around the world experience widespread downtime earlier on Tuesday, November 18, disrupting access to major online platforms and services.
The companies affected by the glitch included X (formerly Twitter), OpenAI, Canva, Spotify, among popular news websites in Nigeria and beyond.
In a statement on X, Cloudflare’s Chief Technology Officer (CTO), Dane Knecht, stated that the widespread internet disruption was not the result of an attack but a technical issue within its network that snowballed into broad degradation across Cloudflare’s network and services.
Knecht wrote: “I won’t mince words: earlier today we failed our customers and the broader Internet when a problem in @Cloudflare network impacted large amounts of traffic that rely on us.
“The sites, businesses, and organisations that rely on Cloudflare depend on us being available and I apologise for the impact that we caused.”
He explained that the outage was caused by a “latent bug in a service underpinning our bot mitigation capability” that started to crash after a routine configuration change.
Knecht stated, “Transparency about what happened matters, and we plan to share a breakdown with more details in a few hours.
“In short, a latent bug in a service underpinning our bot mitigation capability started to crash after a routine configuration change we made. That cascaded into a broad degradation to our network and other services. This was not an attack.”
The CTO described the outage and the time it took to resolve it as “unacceptable,” noting that Cloudflare has begun work to prevent a recurrence.
He added: “That issue, the impact it caused, and time to resolution is unacceptable. Work is already underway to make sure it does not happen again, but I know it caused real pain today. The trust our customers place in us is what we value the most and we are going to do what it takes to earn that back.”
Giving an update on service recovery, Knecht said traffic flowing through its network was restored by approximately 14:30 UTC, which was the top priority.
However, he said additional work was required to fully restore the control plane — including Cloudflare’s dashboard and APIs used by customers to configure services.
“The control plane should now be fully available. We are monitoring those services and continuing to ensure that everything is fully operational,” the CTO added.
Knecht said the company will share a complete walkthrough of the incident in the coming hours, including what went wrong and the measures being taken to prevent a similar disruption in the future.
The disruption on Tuesday comes weeks after a major Amazon Web Services (AWS) outage threw more than 1,000 websites and applications offline. Microsoft Azure also suffered service interruptions shortly after the AWS incident.
The incident highlights the growing dependency of websites and online services on major infrastructure providers like Cloudflare, which manage large volumes of Internet traffic and security for millions of sites globally.